Designing a Performant Pagination Solution in Mongo
How to build a performant pagination solution in Mongo?
1. Introduction
Whenever we want to display large amounts of data to a user, paginating the database response should be our first option.
Implementing pagination itself might be easy, but creating a performant solution is a bit more complicated and involves several tradeoffs.
In this article, we’re going to look into different pagination options in MongoDB and see their main benefits and downsides.
2. Pagination with Skip and Limit
The most common approach to pagination is to use Mongo’s skip and limit. It is really straightforward and easy to get started, but there is a big issue: the larger the skip value, the slower the requests get.
Let’s imagine we are serving the requests using the following controller:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
const db = require('../../db');

module.exports = async (req, res) => {
    const { limit, offset } = req.query;

    const units = await db.collection('units')
        .find({})
        .skip(Number(offset))
        .limit(Number(limit))
        .toArray();

    const documentsCount = await db.collection('units').countDocuments({});

    res.send({
        data: units,
        pagination: {
            hasNextPage: documentsCount > Number(offset) + Number(limit),
            nextOffset: Number(offset) + Number(limit)
        }
    });
};
Here’s a graph which shows the request duration for a database with over 5,000,000 records:
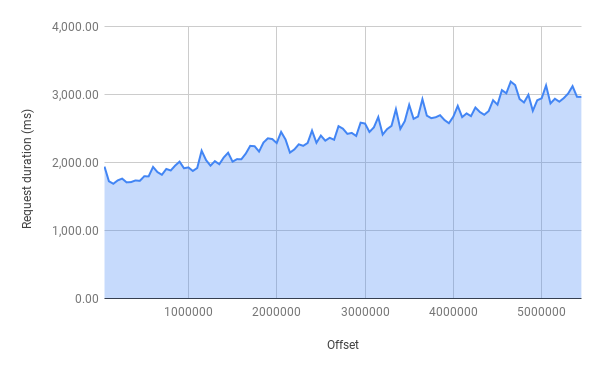
As we can see, the larger the offset, the slower the request gets. For example, compared to offset 0, an offset of 5,000,000 takes more than 50% longer - the graph looks very much like O(n).
Where exactly is the issue?
In order to find the root cause of the apparent slowdown, we can use Mongo’s explain to understand the exact logic of the query. Let’s execute the following command in the Mongo shell:
1
db.units.find({}).limit(20).skip(1000000).explain("executionStats")
We should see a response like this:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
{
   "executionStats":{
      "executionSuccess":true,
      "nReturned":20,
      "executionTimeMillis":792,
      "totalKeysExamined":0,
      "totalDocsExamined":1000020,
      "executionStages":{
         "stage":"LIMIT",
         "nReturned":20,
         "executionTimeMillisEstimate":70,
         "works":1000022,
         "advanced":20,
         "needTime":1000001,
         "needYield":0,
         "saveState":1000,
         "restoreState":1000,
         "isEOF":1,
         "limitAmount":20,
         "inputStage":{
            "stage":"SKIP",
            "nReturned":20,
            "executionTimeMillisEstimate":65,
            "works":1000021,
            "advanced":20,
            "needTime":1000001,
            "needYield":0,
            "saveState":1000,
            "restoreState":1000,
            "isEOF":0,
            "skipAmount":0,
            "inputStage":{
               "stage":"COLLSCAN",
               "nReturned":1000020,
               "executionTimeMillisEstimate":57,
               "works":1000021,
               "advanced":1000020,
               "needTime":1,
               "needYield":0,
               "saveState":1000,
               "restoreState":1000,
               "isEOF":0,
               "direction":"forward",
               "docsExamined":1000020
            }
         }
      }
   }
}
Digging further, we need to look at the key executionStats. Examining the root-level keys totalDocsExamined and nReturned, we can see that in order to serve the skip and limit query with offset 1,000,000, the database needs to scan 1,000,020 records while returning just 20. What a waste of resources!
In an ideal world, whenever we scan a record, we would like to also return it (i.e. the ratio between totalDocsExamined and nReturned should be 1:1). Keeping this in mind helps us to write very efficient database queries.
3. Pagination with Cursor
Pagination with a cursor is one possible alternative to the skip and limit approach.
Instead of returning the numerical offset in the response data, the response should contain a reference to the next item in the list. When making a query to fetch the next page of the data, we have to pass the returned reference back to the query instead of the numerical offset.
If the referenced field is properly indexed, we should see constant-time performance. Let’s imagine that we have the following controller:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
const { ObjectId } = require('mongodb');
const db = require('../../db');

module.exports = async (req, res) => {
    const { limit, offset } = req.query;

    const query = offset ? { _id: { $gt: new ObjectId(offset) } } : {};

    const units = await db.collection('units')
        .find(query)
        .sort({ _id: 1 })
        .limit(Number(limit))
        .toArray();

    res.send({
        data: units,
        pagination: {
            nextOffset: units.length ? units[units.length - 1]._id : null
        }
    });
};
As we can see, instead of returning the offset as a number, we return the ID of the last item in the array, which tells us where we left off. The next time a client passes an offset to the request, we query it using $gt. Note the explicit sort on _id: the $gt comparison only yields correct pages if the records are returned in the same order every time.
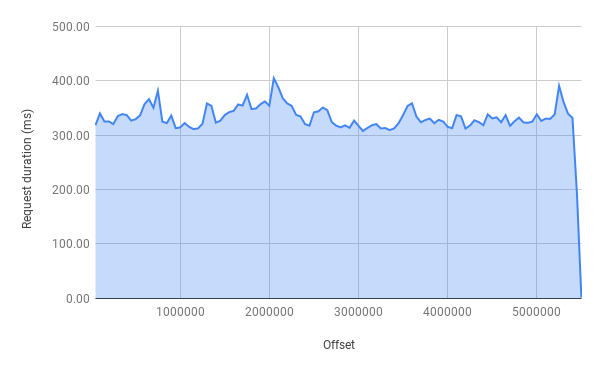
Looking at the graph above, we can see that no matter how far we are in traversing the list of records, the performance stays roughly the same - O(1).
Executing explain reveals that this time totalDocsExamined is exactly equal to nReturned.
1
2
3
4
db.units
    .find({_id: {$gt: ObjectId('600f46ae04d46f5b82acbab0')}})
    .limit(50000)
    .explain('executionStats')
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
{
   "executionStats":{
      "executionSuccess":true,
      "nReturned":50000,
      "executionTimeMillis":39,
      "totalKeysExamined":50000,
      "totalDocsExamined":50000,
      "executionStages":{
         "stage":"LIMIT",
         "nReturned":50000,
         "executionTimeMillisEstimate":2,
         "works":50001,
         "advanced":50000,
         "needTime":0,
         "needYield":0,
         "saveState":50,
         "restoreState":50,
         "isEOF":1,
         "limitAmount":50000,
         "inputStage":{
            "stage":"FETCH",
            "nReturned":50000,
            "executionTimeMillisEstimate":2,
            "works":50000,
            "advanced":50000,
            "needTime":0,
            "needYield":0,
            "saveState":50,
            "restoreState":50,
            "isEOF":0,
            "docsExamined":50000,
            "alreadyHasObj":0,
            "inputStage":{
               "stage":"IXSCAN",
               "nReturned":50000,
               "executionTimeMillisEstimate":1,
               "works":50000,
               "advanced":50000,
               "needTime":0,
               "needYield":0,
               "saveState":50,
               "restoreState":50,
               "isEOF":0,
               "keyPattern":{
                  "_id":1
               },
               "indexName":"_id_",
               "isMultiKey":false,
               "multiKeyPaths":{
                  "_id":[

                  ]
               },
               "isUnique":true,
               "isSparse":false,
               "isPartial":false,
               "indexVersion":2,
               "direction":"forward",
               "indexBounds":{
                  "_id":[
                     "(ObjectId(\\'600f46ae04d46f5b82acbab0\\'), ObjectId(\\'ffffffffffffffffffffffff\\')]"
                  ]
               },
               "keysExamined":50000,
               "seeks":1,
               "dupsTested":0,
               "dupsDropped":0
            }
         }
      }
   }
}
As we’re using the comparison operator when requesting records, we always have to ensure that the offset value is orderable and unique.
For example, it’s perfectly fine to use an auto-incrementing integer, a Mongo ObjectId, or a ULID, all of which sort by creation time. A random UUID, on the other hand, can’t be used as an offset, as we have no way to determine the exact order of the records.
On the other hand, there’s a major drawback to the cursor-based approach. Namely, we can’t jump to a specific page in the list of records as we can with skip and limit.
4. Bucket-based Pagination
Bucket-based pagination offers a solution to the previous problem: it’s significantly faster than the skip-based approach, and it still allows jumping to a specific page.
Let’s imagine that all of the records in the units collection are in the following form:
1
2
3
4
5
6
7
8
{
   "_id":"6014950f48addb3be286c500",
   "area":"A100100",
   "year":"2000",
   "geo_count":"96",
   "ec_count":"130",
   "user":"6014962f3200153be21c7834"
}
The bucket-based approach groups multiple records into a single bucket document:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
{
    "_id": "6014a865562a6ea746d3c4cb",
    "user": "6014962f3200153be21c7834",
    "count": 5000,
    "units": [
        {
            "_id": "6014950f48addb3be286d718",
            "area": "A300900",
            "year": "2000",
            "geo_count": "6",
            "ec_count": "12"
        },
        {
            "_id": "6014950f48addb3be286d71d",
            "area": "A301600",
            "year": "2000",
            "geo_count": "3",
            "ec_count": "6"
        },
        {
            "_id": "6014950f48addb3be286d722",
            "area": "A302400",
            "year": "2000",
            "geo_count": "3",
            "ec_count": "3"
        }
    ]
}
For example, if we decide to have 5,000 elements in a single bucket, then instead of having 5,000,000 documents in the collection, we end up with just 1,000.
The controller for traversing the records looks like this:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
const db = require('../../db');

module.exports = async (req, res) => {
    const { page = 0 } = req.query;

    const [bucket] = await db.collection('grouped_units')
        .find({})
        .skip(Number(page))
        .limit(1)
        .toArray();

    const bucketsCount = await db.collection('grouped_units')
        .countDocuments({});

    res.send({
        data: bucket ? bucket.units : [],
        pagination: {
            hasNextPage: bucketsCount > Number(page) + 1,
            nextPage: Number(page) + 1
        }
    });
};
Note that once again, we’re using skip, but this time it’s way more efficient. Even if we are at the end of the records, we just need to scan a maximum of 1,000 documents compared to the situation in Section 2, where we had to scan almost 5,000,000.
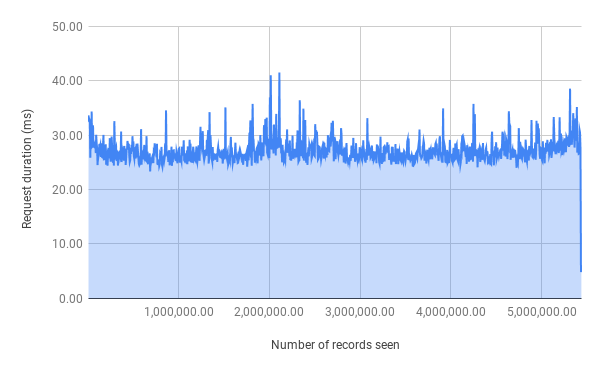
Looking at the request duration graph, we can see that it’s practically flat. The skip is still linear in the number of buckets, but with 1,000 buckets instead of 5,000,000 records, the difference between the first and the last page is negligible.
Unfortunately, there are no silver bullets in this game and this method has its downsides. The most important one is probably that it’s more complex to insert, delete or update an individual record inside a bucket.
For example, in order to insert a record into a bucket, we have to execute this query:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
db.collection('grouped_units').updateOne({
    user: user.id,
    "count": {
        $lt: 5000
    }
}, {
    $push: {
        units: unit
    },
    $inc: {
        "count": 1
    },
    $setOnInsert: {
        user: user.id
    }
}, {
    upsert: true
});
The query looks up a single bucket in the grouped_units collection which has fewer items than the threshold of 5,000 and pushes the record there. If every bucket is full, the upsert creates a new one.
Because the maximum document size in Mongo is 16MB, we have to make sure that a bucket never exceeds that limit. Hence, we should be careful when storing large documents inside the buckets.
5. Conclusion
Returning a paginated response is required for almost every client-facing application.
Even though paginating response data with Mongo’s skip and limit is relatively straightforward, skip makes the queries O(n).
To create a performant constant-time pagination solution, we need to either use the cursor-based approach or store the data in buckets.