Kafka Log Compaction
Kafka offers an alternative to the time-bound retention policy, called log compaction. This article takes a deep dive into the relatively unknown capability of Kafka.
Kafka has become one of the most prominent players in the event streaming space. Both small companies and large corporations have found Kafka to be extremely beneficial for achieving their business goals.
Kafka is a tool with a lot of lesser-known features that can be put to good use. One such feature is log compaction.
This article takes a deep dive into log compaction and introduces its theoretical and practical sides.
The article expects that the reader is familiar with Kafka basics such as partitions and topics.
1. What is Log Compaction?
At its core, Kafka is a commit log. That is, there’s one log per partition. Every time a record is dispatched to Kafka, the entry is appended to the end of the log of a certain partition. The exact partition can be, for example, determined randomly or by the key of the message.
 Figure 1.1. Internals of a Kafka topic without log compaction
For example, in the image above, we can see a topic with two partitions. Once we produce an event with key 2, it gets appended to the end of the log of partition 2.
The more messages we add, the more storage space we need for persistence. To control the amount of storage needed, we have to control when Kafka deletes the messages from the commit log. The two standard options for controlling the retention are log.retention.hours and log.retention.bytes. The first states how many hours a message can stay in the commit log before it gets wiped. The second controls how large the commit log can grow in bytes before Kafka removes the older messages.
However, there’s an alternative to the time-bound retention policy. This is called log compaction. Log compaction guarantees that Kafka stores at least one message for every key per partition. If there are two messages with the same key in the same partition, then the older one may be scheduled for deletion.
 Figure 1.2. Internals of Kafka topic with log compaction
In the image above we can see that the older message with key 1 in partition 1 is scheduled for deletion. The same goes for two of the three messages with key 2 in partition 2. On the other hand, messages with keys 4 and 6 won’t be deleted, as they only occur once.
What are the potential practical applications for log compaction? The most common use case is for recovering the state of a Kafka consumer in case of issues. For example, if a consumer needs to materialize the email changes in memory and find out the latest email for a user with ID 2, then every time it restarts, it needs to go through all the messages to get the latest email for user 2. By storing the intermediate state in a Kafka topic with log compaction enabled, the consumer can read the latest state from the compacted topic before proceeding with consuming the latest entries from the raw topic.
On top of that, log compaction is an excellent tool for complying with GDPR-like regulations, because it allows us to remove unwanted data from a topic.
2. Log Compaction Internals
Even though a single partition of a topic looks like one big log file, this is not the case. Underneath, Kafka splits a single partition into multiple smaller segments stored in different files.
For example, when we go through the storage layer of a partition, we will see a file structure similar to this:
1
2
3
4
5
6
7
-rw-rw-r--  1 root root        0 nov    1 00:02 0000.index
-rw-rw-r--  1 root root      140 nov    1 00:02 0000.log
-rw-rw-r--  1 root root       12 nov    1 00:02 0000.timeindex
-rw-rw-r--  1 root root 10485760 nov    1 00:03 0006.index
-rw-rw-r--  1 root root       70 nov    1 00:03 0006.log
-rw-rw-r--  1 root root       56 nov    1 00:03 0006.snapshot
-rw-rw-r--  1 root root 10485756 nov    1 00:03 0006.timeindex
Kafka creates quite a few files. The most important ones in the context of log compaction are the ones ending with the suffix .log (i.e. 0000.log and 0006.log).
These two files contain the actual messages dispatched to Kafka. 0000.log is the inactive segment. Kafka has closed that file and doesn’t append any messages to it. 0006.log, on the other hand, is the active segment to which Kafka appends new messages. The file name indicates the offset of the first message in the file.
Kafka compacts the log in two passes over the inactive log segments. 1
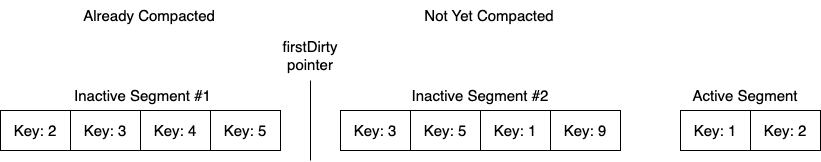 Figure 2.1. Layout of a Kafka Topic During Compaction
During the first pass, the cleaner thread iterates over all the messages that are to the right of the firstDirty pointer, excluding the active segment. It builds a map out of all the seen messages, where the key is the message key and the value is the highest offset seen for that key.
During the second pass, it goes through all the messages (both already compacted and not yet compacted ones) and checks every message against the map. A message is kept only if its key doesn’t appear in the map or its offset is at least as high as the offset stored in the map for its key. In other words, only the latest message for every key survives, and all older duplicates are discarded.
The surviving messages are written to new segment files. Eventually, the cleaner thread swaps the old segment files with the new ones and moves the firstDirty pointer to the end of the cleaned section.
As log compaction works with the log files of a partition, the compaction is applied only in the context of a single partition. Hence, if messages with key 2 end up in both partitions 1 and 2, then they aren’t compacted against each other.
Log compaction doesn’t change any offsets in a partition. The retained messages keep their original offsets, so the offsets in a compacted partition have gaps.
3. Log Compaction in Practice
The bare minimum to get log compaction working is to set cleanup.policy for a topic to compact. For example, creating a topic with the following command enables log compaction:
1
bin/kafka-topics.sh --create --bootstrap-server localhost:9092 --topic email_topic --partitions 1 --config cleanup.policy=compact
However, just enabling log compaction may not be sufficient. Kafka has many options for controlling compaction in detail.
3.1. Log Compaction Configuration Knobs
If we want to limit the maximum time duplicate keys can stay in the log before they’re compacted, we have the max.compaction.lag.ms configuration option. Once the messages in an inactive segment are older than max.compaction.lag.ms, the segment becomes eligible for compaction regardless of the conditions below.
Otherwise, Kafka compacts a partition only when both of the following hold: the messages have existed longer than min.compaction.lag.ms, and the not-yet-compacted part of the log makes up a larger share of the total log size than min.cleanable.dirty.ratio (a ratio between 0 and 1, defaulting to 0.5).
3.2. Deleting Entries from Kafka
As it’s possible to use Kafka in a database-like setting, it’s also possible to delete records from the topic. For deleting a record, we need to produce a message with the same key and a null value (aka a tombstone).
Once Kafka compacts a key marked for deletion, the consumers will see only the tombstone. Once the delete.retention.ms period passes (defaults to one day), Kafka cleans up the tombstones themselves and the deleted keys completely disappear from the partition.
If a consumer keeps state about a key, then it has to read the tombstone from the topic within delete.retention.ms. Otherwise, the consumer will miss the tombstone and won’t remove the key from its internal state, as Kafka will have removed the tombstone from the log completely.
As mentioned previously, this allows us to comply with GDPR. If a customer wants their data to be completely wiped, we have to enable log compaction, set a suitable deletion retention period, and produce a tombstone for the customer’s key. After the period passes and the compaction runs, the data will be removed from the Kafka topic. Naturally, this only works if the messages are keyed by the customer.
4. Conclusion
The article took a look at Kafka log compaction. Log compaction offers an alternative to the standard time-based message retention policy. When log compaction is enabled, Kafka cleans up the entries with duplicate keys, keeping just the latest one.
The use cases of a log compacted topic vary from storing the intermediate state of a Kafka consumer to complying with GDPR.